Open lakehouse
Open lakehouse
Run an open lakehouse on Quake AI: Apache Iceberg tables over S3-compatible storage, federated SQL through Trino, and dashboards in Metabase or Superset. You operate the catalog, query engine, and BI hosts; Quake AI provides compute, networking, block volumes, and Object Storage buckets. This architecture targets data engineers who want schema evolution and time travel on the lake without a proprietary table format or per-query warehouse billing.
What this is for#
Data engineering teams that want an open lakehouse on infrastructure they control compose three tiers: a table catalog and object store for Iceberg files, a federated query engine that reads those tables alongside Postgres or ClickHouse, and a BI layer for analysts. Quake AI provides CPU compute, block storage for container data, and S3-compatible Object Storage for a durable warehouse root; you operate MinIO or the platform bucket, the Iceberg REST catalog, Trino, and the dashboard tool. The outcome is a self-hosted lakehouse stack deployable from validated OpenTofu templates and their companion deployment pages.
Reference architecture#
Download diagram: SVG, PNG, and PDF.
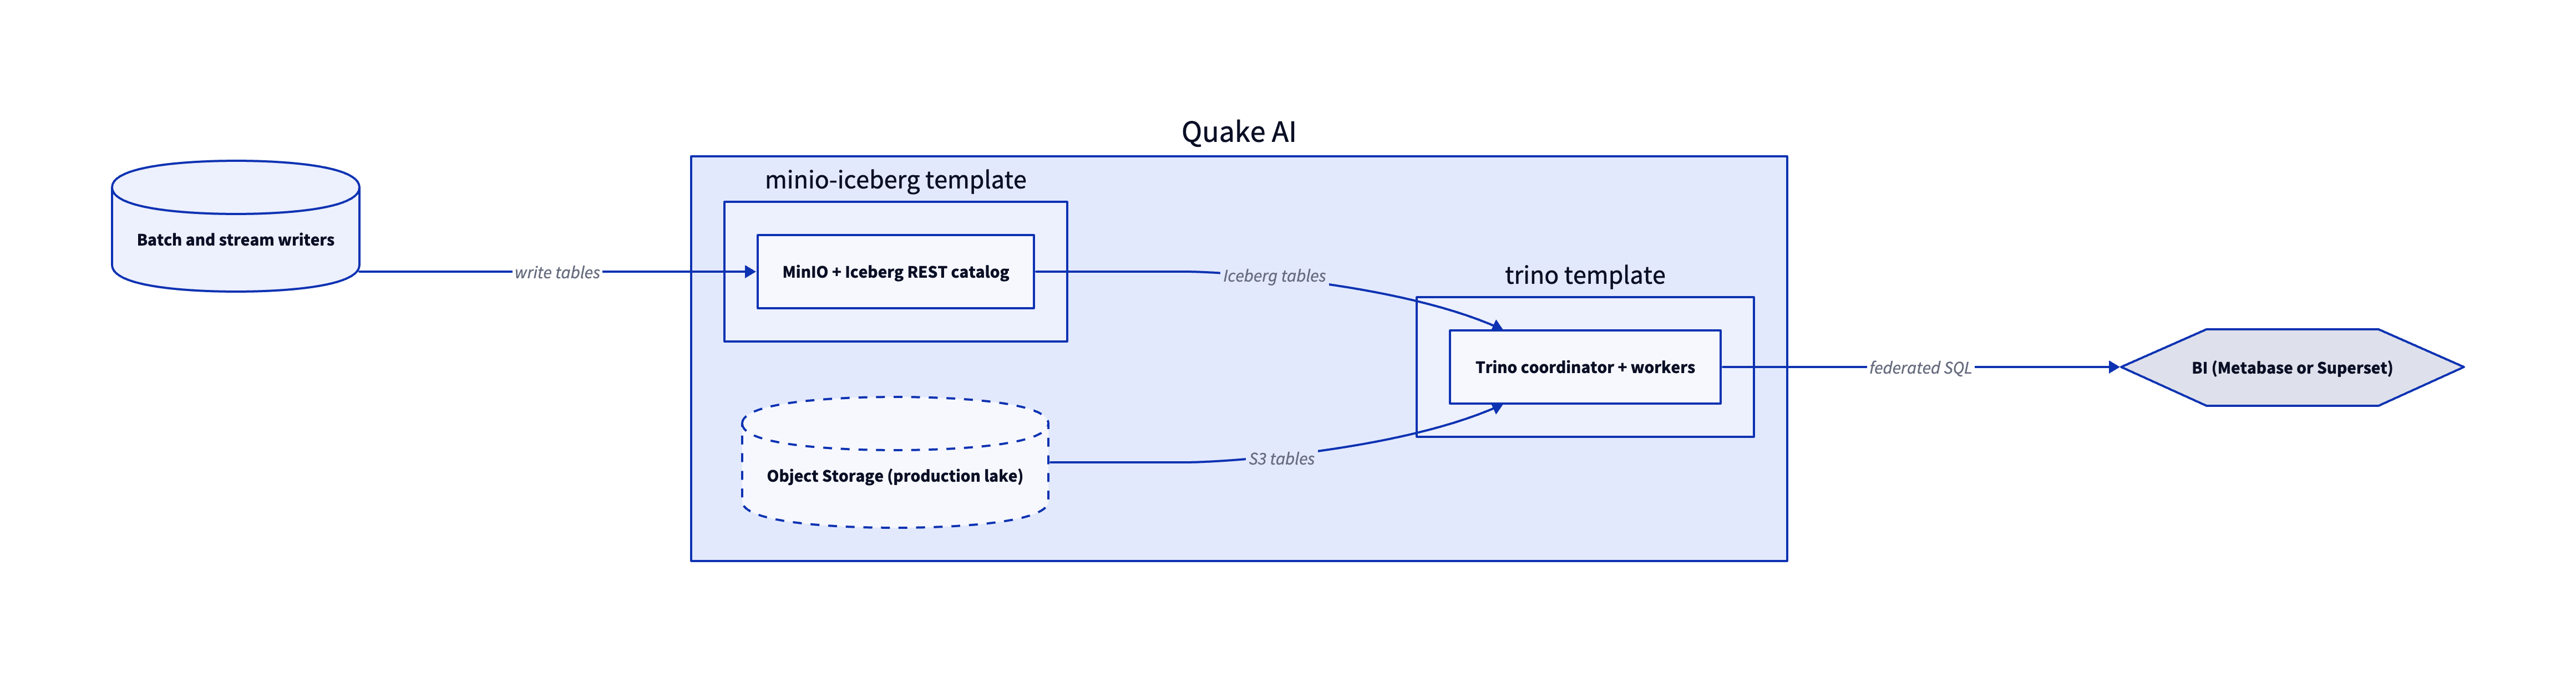
The lakehouse is four tiers plus a production storage variation. Each maps to the diagram and to the template that builds it.
-
Writers and pipelines. Batch jobs, stream consumers, and notebook exports write Parquet or ORC files and register Iceberg snapshots through the REST catalog.
-
Lake and catalog. The minio-iceberg template provisions MinIO and an Iceberg REST catalog on a single instance with data on Block Storage. For a lake that outlives one VM, point table storage at S3-compatible Object Storage buckets in the same project.
-
Federated query. The Trino template runs a coordinator and workers that register the Iceberg catalog, optional Postgres or ClickHouse sources, and built-in sample catalogs for smoke tests.
-
BI layer. Apache Superset connects to Trino as a database. Metabase uses the same Trino JDBC connection. Analysts build dashboards and SQL Lab queries without copying data out of the lake.
-
Production lake variation. Replace the bundled MinIO endpoint with the platform Object Storage gateway so table files and metadata survive instance rebuilds. Trino reads the same Iceberg REST URI and S3 credentials you configure after apply.
Services involved#
| Service | Role in this architecture | Docs |
|---|---|---|
| Compute | MinIO, Iceberg REST catalog, Trino, and BI hosts | Compute |
| Block Storage | Docker data volumes for catalog and query containers | Block Storage |
| Object Storage | Durable Iceberg warehouse root in production | Object Storage |
| Network | Private subnets and security groups between tiers | Network |
Get started#
Each template below pairs with a step-by-step deployment page. Stand up the lake and catalog first, wire Trino to the REST endpoint, then connect Superset or Metabase.
- MinIO + Iceberg template and its deployment walkthrough: MinIO, the Iceberg REST catalog, and a bootstrap warehouse bucket on one instance.
- Trino template and its deployment walkthrough: federated SQL over Iceberg, Postgres, ClickHouse, and sample catalogs.
- Apache Superset template and its deployment walkthrough: SQL Lab and dashboards over Trino.
- ClickHouse template and its deployment walkthrough: optional column store Trino can query beside Iceberg tables.
- Object Storage how-to: upload a file: land files in the bucket you register as the Iceberg warehouse root.
- OpenTofu template library: browse validated IaC starting points for the tiers above.
Estimate the cost#
Monthly cost estimate
Pricing calculator ↗Sized as a custom package on dedicated vCPU.
Monthly total for the required template above. Use the configurator below to add optional pieces and see the total update.
What each resource is for
MinIO + Iceberg REST catalog host
m2a.large · 2 dedicated vCPU, 8 GiB RAM, 0.5 Gbps
Runs MinIO (S3-compatible object storage) and an Apache Iceberg REST catalog in Docker, with table data on an attached block volume.
MinIO plus the REST catalog run on 2 vCPU and 8 GiB RAM. Size up the instance and data volume for heavy ingest or large curated layers.
Compute shown per role at custom-package rates ($29/dedicated vCPU, $7.25/shared vCPU, $1/GiB RAM). The headline above is the billed total: the cheaper of a named plan and the custom package, plus add-ons.
Included in baseline
m2a.large
2 dedicated vCPU, 8 GiB RAM, 0.5 Gbps
Compute + RAM rate basis
2 vCPU + 8 GiB RAM at $29/dedicated vCPU, $7.25/shared vCPU, $1/GiB RAM (regular). Totals apply the flat −$5/mo package promotion.
Block storage (80 GiB)
80 GiB at $0.08/GiB/mo
Public IP (included)
1 included with the custom package
Package promotional discount
Flat −$5.00/mo on the custom package (same promotion as named plans).
Included at no charge
These line items are zero on Quake AI. Many other providers meter them separately.
Data transfer (inbound and outbound)
Unlimited data transfer on every plan; Quake AI does not meter per-GB egress.
AWS, GCP, and Azure meter outbound transfer per GB. DigitalOcean and Hetzner include an allowance on compute plans, then charge overage.
Learn morePrivate networking
Private networks, subnets, Neutron routers, and security groups are included with the plan.
VPC objects are usually free to create elsewhere, but NAT gateways bill hourly plus per-GB processed. Quake AI uses router SNAT with no separate NAT line item.
Control-plane API requests
OpenStack API calls for provisioning and management are included.
Some managed services on other clouds meter API calls or charge for premium control-plane features.
Configure your estimate
Check the add-ons you plan to deploy to build a monthly total. Nothing is selected to start, so the total below begins at the baseline.
Starting template
The required baseline, always included.
Dev/test vs production
Start on shared CPU for dev/test, then promote to dedicated for production with a flavor resize. The network, storage, and template stay the same.
Dev/test on shared CPU
Burstable s1a flavors; suited to prototyping and low or bursty load.
Production on dedicated CPU
The headline estimate above; predictable steady-load performance.
Saves $49.50/mo while you build on shared CPU.
Shared flavors carry less RAM (m2a.large (8 GiB RAM) -> s1a.small (2 GiB RAM)). A resize reboots the instance; data on attached volumes persists. Size the dedicated flavor for the RAM your production workload needs.
Pricing data last validated: . For current rates, check quake.ai/pricing.
Considerations and limits#
- Self-hosted stack. Quake AI provides compute, networking, and storage. Your team operates MinIO or the platform bucket, the Iceberg REST catalog, Trino, and the BI tool under the shared responsibility model.
- Bundled MinIO is a dev host. The minio-iceberg template colocates MinIO and the REST catalog for integration testing. Point production table storage at Object Storage so files survive instance replacement.
- CPU-only compute. Compute is AMD EPYC with no GPU option (compute FAQ). Trino runs on CPU; GPU-accelerated engines need a different hosting path.
- Catalog wiring is manual after apply. Trino reads Iceberg when you set
iceberg_rest_uriand S3 endpoint values in tfvars or catalog files on the instance. Superset and Metabase need the Trino JDBC URL after Trino is reachable. - Flat egress. Quake AI applies a no-egress-fee policy for outbound transfer, which helps lakehouses that move large Parquet files between regions or tools.
- Three US regions. All current regions are in the United States.
- Compliance posture. Quake AI holds SOC 2 Type I and Type II attestations and SOC 3. See Compliance and certifications for the platform scope.